Two hats at AGNTCon + MCPCon
Last week I wore two hats at once. I went to AGNTCon + MCPCon as part of the Agentic AI Foundation team, and I went as a builder. I'm building agentic workflows for myself, for my workshops and for clients. It turns out that's a great combination. Super fun!
These are my notes as a builder. They aren't positions of the Agentic AI Foundation.
Last week I wore two hats at once. I went to AGNTCon + MCPCon as part of the Agentic AI Foundation team, and I went as a builder. I'm building agentic workflows for myself, for my workshops and for clients. It turns out that's a great combination. Super fun!
#The event
AGNTCon + MCPCon North America ran October 22 and 23 in San Jose. It used to be the MCP Dev Summit, and it's grown into two days and more than 150 talks across eleven tracks.
The Agentic AI Foundation (AAIF) also announced four new projects:
- Agent Skills, from Anthropic
- Open Responses, from OpenAI
- OpenEnv, from Hugging Face and Meta's PyTorch team
- OpenSandbox, from Alibaba
That brings the foundation to ten projects, alongside MCP, goose, AGENTS.md, A2A and others.
The hallway was the best part. A lot of the people there are building the same kinds of things I am, and running into the same walls.
#Two days earlier, a bridge crew
I didn't arrive cold. On October 20 I gave my To Boldly Go talk at All Things Open in Raleigh. It's about LCARS Online, a Star Trek-themed dashboard where a crew of small agents analyzes NASA exoplanet data on my laptop, with the model running locally too.
The rule that made it work was simple: let the model decide what to check, and let code do the math. Each station gets one job, a short list of tools and a typed output. Qwen3.5-9B on an M1 can handle that. It can't be trusted with numbers, so it never touches them.
So when I got to San Jose, I already had a strong opinion about small models.
#My seat
My day job is open source TPM at AAIF. I support the working groups, help new projects and new working groups get started, and try to keep all of it moving in the open. I've spent a long time in open source governance, and one thing I've learned is that governance decisions show up in code. Who can change a spec, how much notice people get, and what gets a shared name all shape what builders actually ship.
This week I got to watch that up close, at the heart of where agentic stack decisions are being made. Then I went home and built with it.
#Where governance met my code
Here are three places a talk, and the decision behind it, connect to what I'm building at Wildflower Software.
#Small, local, task-specific models
The PyTorch Foundation talk on small, task-specific models argued for an open set of tools for serving and improving models, instead of betting everything on one big model. It also made the case for models that get faster and cheaper by learning from production feedback.
That's the pattern I already build with. My agents are narrow workers, so each one is a good candidate for a small model that's good at exactly one thing. LCARS showed me the other half too: almost every fix came from reading a failed run. Feedback from real use is how these systems get better.
So one agent in my flower shop demo gets a small local model. The demo exists to talk through the design decisions I'm making in my client's stack, and this is one of them: which jobs need a frontier model and which don't. What works in LCARS, tested on stage and in hallway tracks from PyCon Italia and PyTexas to AGNTCon, is making its way into my client boilerplate and abstractions.
#The new MCP spec
The current MCP spec, version 2026-07-28, is a big one. The core is now stateless, so there's no handshake or session to keep alive, and long-running work moved into a Tasks extension. It went through the open proposal process, and it ships with a feature lifecycle policy that gives at least twelve months' notice before a feature is removed.
Here's a fun surprise: my flower shop demo already speaks 2026-07-28. It's built on FastMCP, and FastMCP 4 added the new protocol while still letting older clients connect. I got the upgrade by reinstalling. What I haven't done is use any of the new features.
I'm early, and that's where the lifecycle policy matters. MCPJam's Can I use MCP? table shows Claude, ChatGPT, VS Code and Copilot supporting 2026-07-28, while Cursor and Slackbot are still on the previous version. Out among public servers, it's earlier still. A late-September census of public MCP endpoints found only 392 that answered a request for the new version, out of thousands that answered the older handshake (the data is on Hugging Face). A year's notice is what lets the ecosystem move at that pace without breaking, and it lets me plan instead of scramble.
What could change in the demo repo:
- Serve the shop's tools over stateless HTTP, which would make hosting much simpler.
- Turn queued approvals into MCP Tasks. A quote waiting on the owner already says "this has NOT been carried out." The protocol could say that too.
- Publish a server card, so other clients can find the shop's tools before they connect.
LCARS could get an experiment of its own. Its missions are long-running flows that pause for the Captain to approve each step, which is what Tasks are for. It doesn't use MCP today, so the first step would be serving the crew's tools over MCP.
MCP Apps came up again and again in the hallway track, on the list of things the experts I talked to are watching. It's the official extension that grew out of MCP-UI. It lets a server ship a small interactive UI that hosts like Claude, ChatGPT and VS Code render inside the chat. An approval card for a quote, with the quote and an Approve button, would be a nice fit when someone uses the shop from one of those apps. The catch: a button in an app calls a tool through the host, and the spec leaves extra approval for those calls up to the host. So the card could be the doorway, but the approval rule still has to live in my code. It's a small experiment for later, not where I'd start.
#A pattern with a name
AAIF's Workflows & Process Integration working group has published a human-approval gate as one of its patterns, along with a "durable wait" for work that waits on a person.
I've built that gate twice already: the approval queue in the flower shop and the Make it so button on the LCARS bridge. In both, the rule lives in code, not in a prompt. It's nice to see something I worked out on my own get a shared name. Shared names are how a pattern goes from "a thing Dawn does" to something a team can reach for.
#Where my agents can't go
Here's the part none of my agents can do: show up at the shop.
The flower shop I work with is the real system behind my demos. The Wildflower Software examples are abstracted from it, but the questions all start here, with what's in the cooler, what came in off the truck and what customers keep asking for.
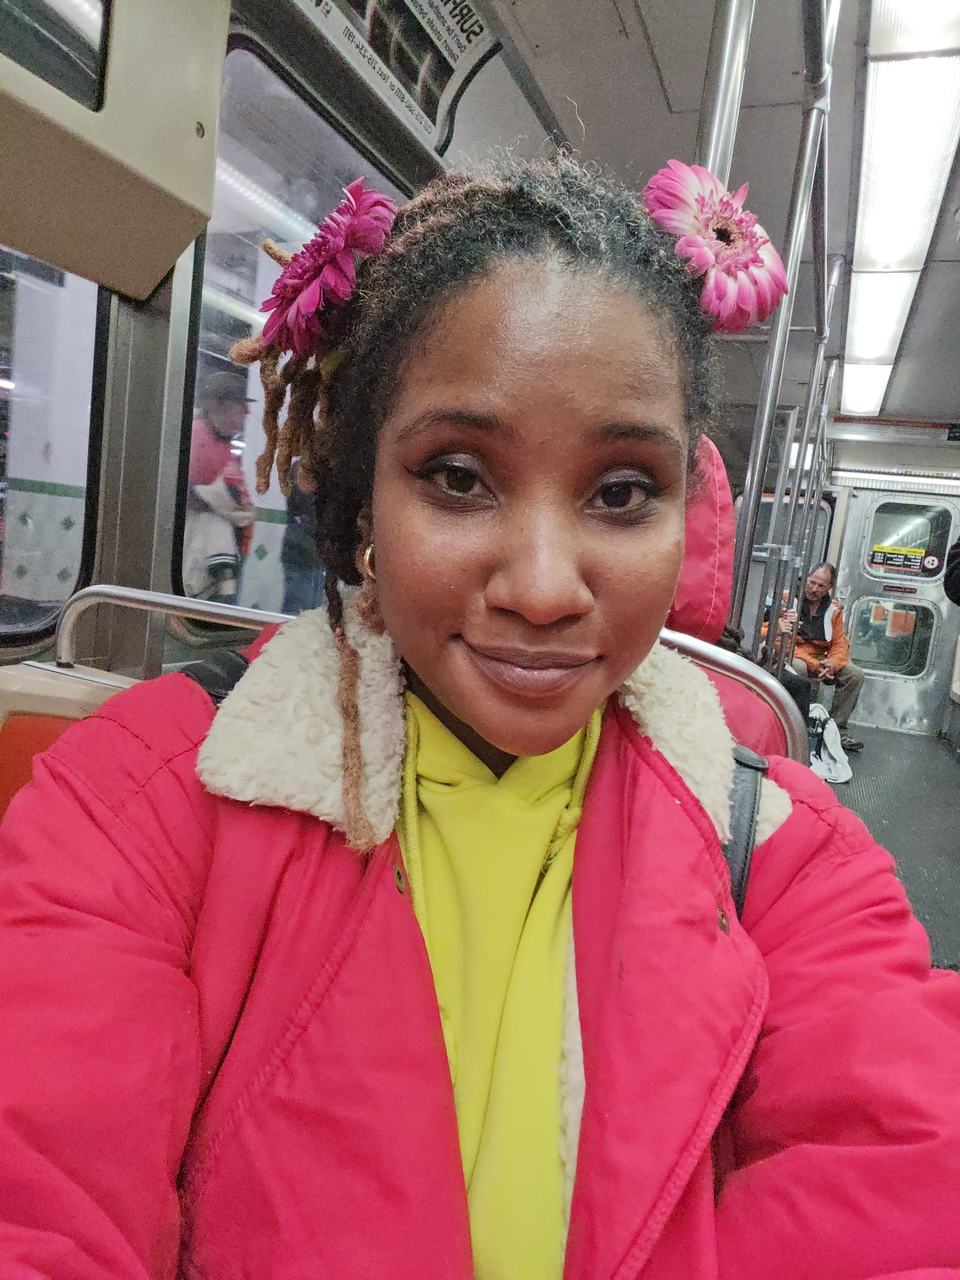
Literally touching grass (and lilies, and gerberas) keeps me honest. The owner knows things no POS export will ever tell me, and the only way I learn them is by being there. Sometimes I ride the train home still wearing some of it.
#Let's see what happens
Governance tells me where the ecosystem is heading. Building tells me whether any of it works yet. Doing both at once is the most fun I've had in a while.
So here's what I'll be trying: a small model on one agent, the flower shop using what the new MCP spec offers, and maybe a LCARS mission running as a Task. I'll write up what works and what breaks. Let's see how my building changes now that I have a front row seat.
About 10 bottles of water (≈5.0 L)
Estimated water used by the AI tools that helped research and draft this post, counted in 500 mL bottles. AI providers don't publish per-chat figures, so this sits between two public benchmarks.
How it's calculated: ~1,400 prompt-equivalents × √(0.26 mL × 50 mL) = 1,400 × 3.6 mL ≈ 5.0 L ≈ 10 bottles
- 0.26 mL: Google's figure for a median Gemini text prompt.
- 50 mL: Mistral's figure for a ~400-token Le Chat response.
- A geometric mean weighs the two evenly, even though they're about 200× apart.
Both figures are self-reported, exclude model training, and count evaporative cooling as water consumed.
Further reading: - How much power and water does AI use? (PCWorld) - Google games numbers to make AI look less thirsty (The Register)
If this post helped, you can support my open source work on Ko-fi.